structural-biology/ai produced the result/Acta Crystallographica Section D Structural Biology 2025 · v2
Neural network fills gaps in protein maps from raw diffraction data
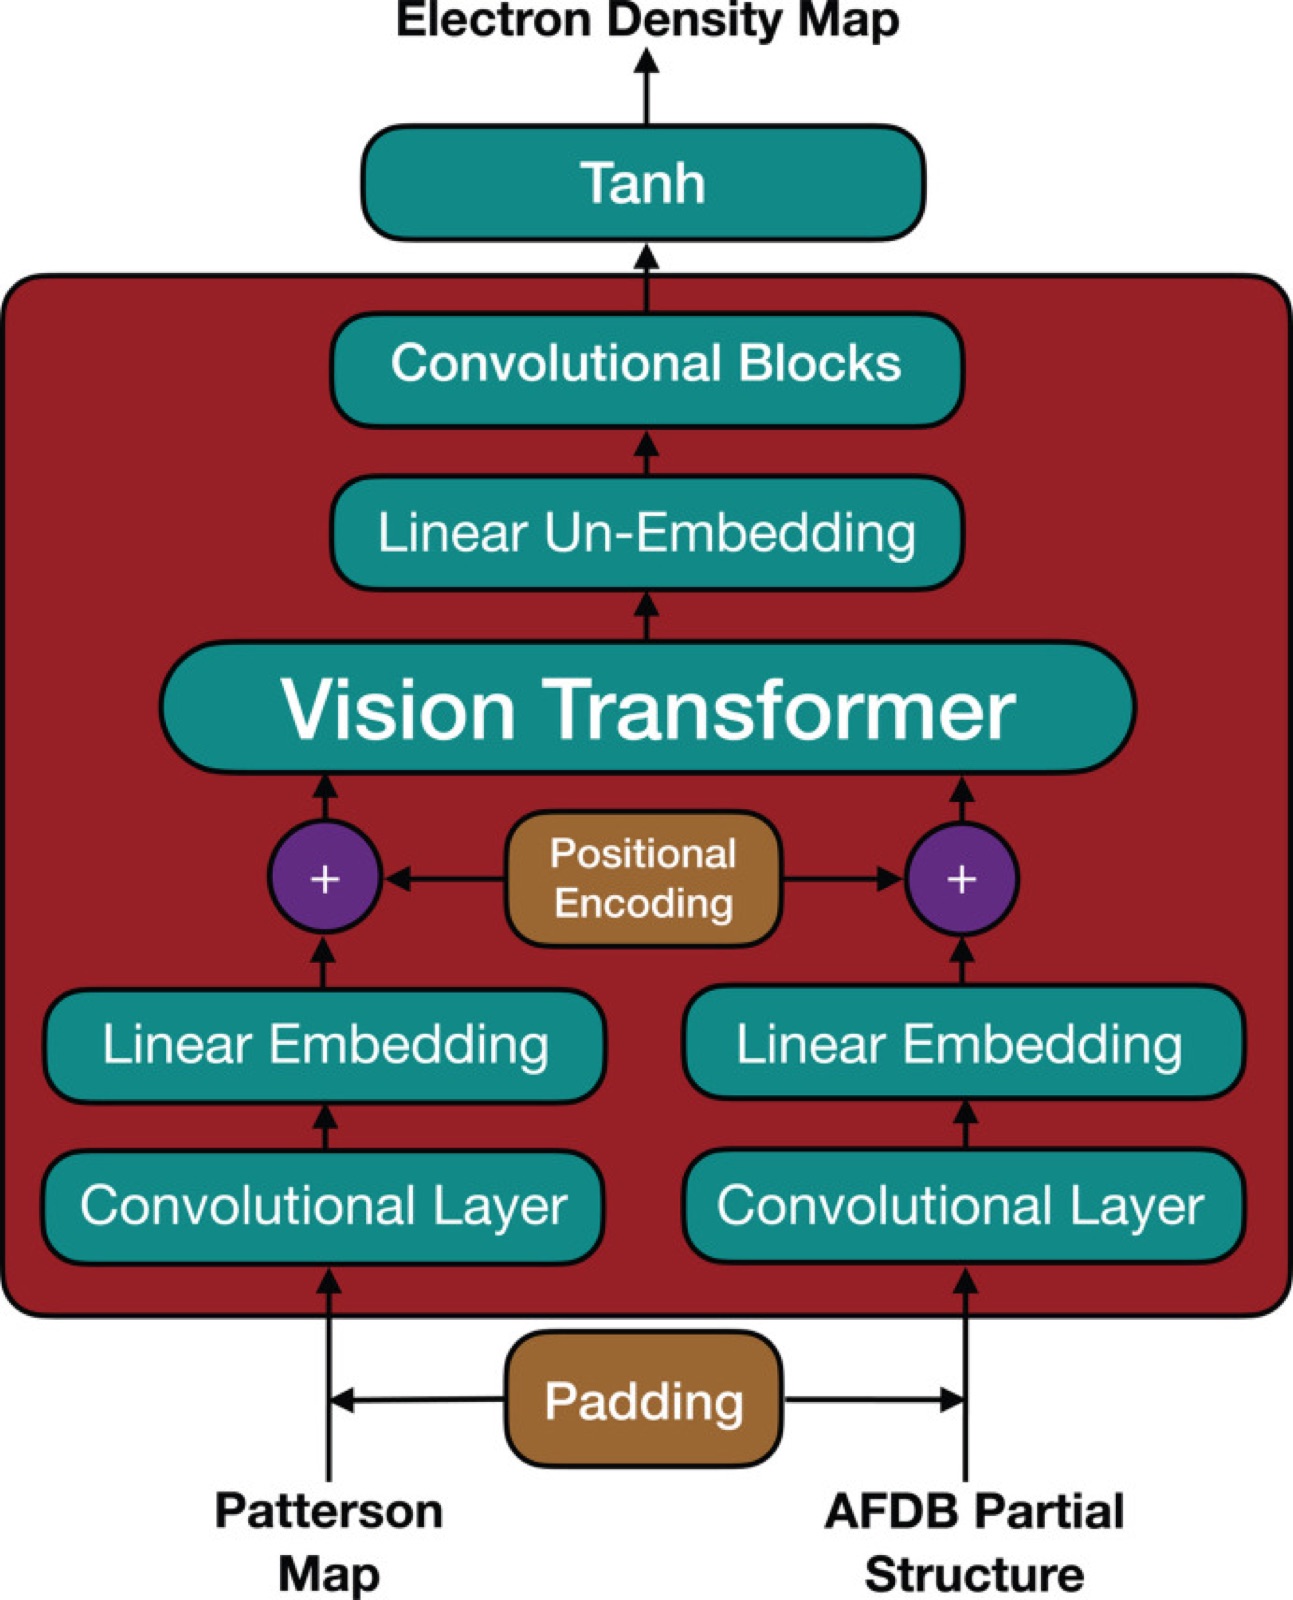
Researchers trained a model called CrysFormer to produce protein electron-density maps from two inputs: a Patterson map computed from diffraction data, and an incomplete predicted template with several residues missing.
spectrum · one line per step, placed by what the step does · bright lines used AI
Completion of partial structures using Patterson maps with the CrysFormer machine-learning model
Acta Crystallographica Section D Structural Biology, 2025
doi:10.1107/s2059798325009659 · record aix-00171 v2 · checked 2026-10-09
- AI was for
- Structure determination
- Model family
- Transformer, Convolutional neural network
- Checked by
- Held-out176556 tested
- Code
- available
The finding the paper is about came from the AI.
What this research was about
To work out the shape of a protein, crystallographers shine X-rays through a crystal of it and record how the beams scatter. The snag is that the detector measures only how strong each scattered beam is, not the timing, or phase, of its wave. Both are needed to rebuild a map of where the electrons sit, and from that the positions of the atoms. One standard trick is to start from a rough guess of the structure, borrowed from a related protein or a computed prediction, and use it to estimate the missing phases. If the guess is incomplete, the resulting map tends to be poor in exactly the regions nobody has guessed yet.
This work tackles that gap-filling step. The researchers built a large collection of short protein pieces, fifteen amino-acid units long, taken from structures already solved by X-ray crystallography. For each piece they computed a Patterson map, a quantity derived straight from the measured intensities without any phase information, and a matching template map built from an AlphaFold Database prediction with a run of three to seven of its fifteen residues deliberately deleted. The question was whether a model could turn that pair into the full map.
Where AI came in
CrysFormer, a hybrid of a three-dimensional vision transformer and a convolutional network, does the central work. It was trained from scratch on pairs of Patterson maps and true electron-density maps, together with the deliberately incomplete templates, and learned to output the full map. The model takes the place of the conventional calculation that would normally be used to improve a partial structure's phases, and in that sense it stands in for an existing piece of crystallographic software rather than for a human judgement.
The surrounding steps were done with ordinary tools: software computed the Patterson and reference maps, matched each fragment to a predicted structure and aligned the two, and afterwards scored the model's maps against the known answer. On a held-out test set of 176,556 examples, the paper reports higher agreement with the true density and smaller phase errors for the model's output than for the same templates processed with the established SIGMAA procedure. The code and data are available.
Written by AIxSci from the checked record below, to give context for readers outside the field. It is not part of the record.
The work
Technical · from the record
The authors trained CrysFormer, a hybrid 3D vision transformer and CNN, to output protein electron-density maps from two inputs: a Patterson map computed directly from simulated diffraction data, and an incomplete template map derived from an AlphaFold Database prediction with 3 to 7 of its 15 residues removed. Training used a synthetic data set of 15-residue fragments in P21 unit cells, built from 589 546 Patterson map and ground-truth density pairs expanded to 1 634 839 examples by generating up to three different residue-omission patterns per pair. On a held-out test set of 64 070 initial examples, the paper reports higher in-model-region Pearson correlation with the ground truth and lower unweighted and FOM-weighted phase errors for the model predictions than for the same partial-structure templates processed with the SIGMAA PARTIAL baseline, both over the full test set and over a 19 436-example subset with the poorest alignment of the AlphaFold-derived template to the ground truth. Pearson correlations of the predictions showed no apparent dependence on the solvent content of the ground-truth unit cell.
How AI was used
A single learned model does the central work. 15-residue fragments were extracted from a basis of nearly 38 000 curated PDB structures, placed in P21 unit cells, and used to compute structure factors with gemmi sfcalc and then Patterson and ground-truth electron-density maps with the CCP4 FFT program at resolution limits binned across 1.75-2.3 A. Matching AlphaFold Database v4 predictions were located through UniProt identifiers from PDBe SIFTS, aligned to each fragment by Needleman-Wunsch sequence alignment and then by structural alignment with the PyMOL align command as a stand-in for molecular-replacement placement, and had a randomly chosen contiguous block of 3 to 7 residues removed from one or both ends to form partial-structure template maps. CrysFormer, a 3D vision transformer with Nystrom approximate attention combined with scale-equivariant 3D convolution and batch-normalisation layers, was then trained from scratch to regress the ground-truth density from the Patterson map and the single same-sized partial-structure template, using mean-squared error plus a negative Pearson correlation term, a Schedule-Free AdamW optimiser under a OneCycle schedule, and data-parallel training over two GPUs. The trained model was run over the held-out test examples, and its predicted maps and derived structure factors were scored with Phenix get_cc_mtz_pdb and CCP4 CPHASEMATCH against the same templates improved by the non-learned SIGMAA PARTIAL procedure.
The shape of the work
Structural · the record, drawn
no AI
Curate PDB fragments
Obtaining raw data, whether by measurement, download or retrieval.
extracted all possible 15-residue fragments without randomly removing any obtained oneswhere the paper describes this · verbatim
no AI
Compute Patterson and ground-truth maps
Cleaning, filtering, normalising or labelling data already obtained.
We again generated structure factors for each example in its final P21 unit cell with the gemmi sfcalc programwhere the paper describes this · verbatim
no AI
Build incomplete AFDB partial-structure templates
Cleaning, filtering, normalising or labelling data already obtained.
We then removed a subset of the residues from the AlphaFold fragments via a sequence of 2–3 random selectionswhere the paper describes this · verbatim
AI
Train CrysFormer on map triples
Fitting model parameters, including fine-tuning an existing model. The AI stood in for conventional algorithm.
We performed a single training run of our model on a training set of 589 546 initial Patterson map–ground truth electron-density pairswhere the paper describes this · verbatim
AI
Predict completed electron-density maps
Running a trained model over new data to predict, classify or score. The AI stood in for conventional algorithm.
the predictions made by our model with the results after applying SIGMAA to the corresponding incomplete partial structure templates on our test exampleswhere the paper describes this · verbatim
no AI
Evaluate maps against ground truth and SIGMAA baseline
Testing outputs against ground truth.
we use the get_cc_mtz_pdb program from the Phenix program suite (Liebschner et al., 2019) to calculate the Pearson correlation coefficientwhere the paper describes this · verbatim
What the record says
Technical · every part carries its own basis
+ in the paper~ our reading− not reported
How to read the quotations. A quotation shows where the paper describes something. It does not quote every value beside it: one passage locates a part of the work, and values without their own quotation are our reading of that passage.
The reported result is the electron-density maps produced by the trained model from Patterson maps and incomplete templates; without the model there is no result.
a hybrid 3D vision transformer and convolutional neural network (CNN) can be trained to complete and improve the templateswhere the paper describes this · verbatim
once again with each associated by up to three partial structures with 3–7 omitted residues, for a total size of 176 556 exampleswhere the paper describes this · verbatim
A repository, https://github.com/sciadopitys/CrysFormer_model_completion, contains our CrysFormer model architecture and training and batch-generation scriptswhere the paper describes this · verbatim
What this paper did not report
Technical · absence is published deliberately
- Trained model weightsWhether the trained model is available is not stated.
- Version of CrysFormerWhich version of the model was used is not stated.
About this article
Record aix-00171, version 2, checked by a person on 2026-10-09. The record describes the paper; it does not assess whether the paper's findings are right. The paper is published under CC-BY; quotations are at most 25 words. How we work · Report an error